 Indietro
Introductory Statistics Chapter 1 Key Concepts
 04:24

Termini in questo insieme (20)
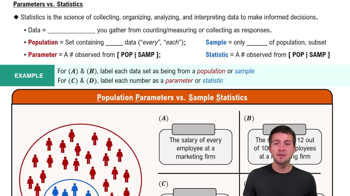
Statistics is the science of collecting, organizing, analyzing, and interpreting data to make decisions.
A population is the entire group of interest, while a sample is a subset of the population used to draw conclusions.
A parameter is a numerical summary describing a characteristic of a population.
A statistic is a numerical summary describing a characteristic of a sample.
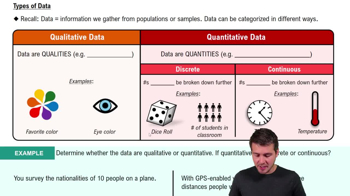
Qualitative data describe categories or qualities; quantitative data represent numerical measurements or counts.
Nominal level classifies data into distinct categories without order (e.g., colors, gender).
Ordinal level classifies data with a meaningful order but no consistent difference between ranks (e.g., rankings).
Interval level has ordered categories with equal intervals but no true zero (e.g., temperature in Celsius).
Ratio level has ordered categories, equal intervals, and a true zero point (e.g., height, weight).
A variable is a characteristic or attribute that can assume different values.
Discrete variables have countable values; continuous variables can take any value within a range.
Descriptive statistics summarize and describe data using measures like mean, median, and graphs.
Inferential statistics use sample data to make generalizations or predictions about a population.
A frequency distribution shows how often each value or category occurs in a data set.
Relative frequency is the proportion or percentage of the total observations for each category.
A histogram is a bar graph representing the frequency distribution of quantitative data.
A stem-and-leaf plot organizes data to show distribution while preserving original values.
A dot plot displays individual data points along a number line to show distribution.
Sampling bias occurs when a sample is not representative of the population, leading to inaccurate conclusions.
A simple random sample is a sample where every member of the population has an equal chance of selection.