 Indietro
Introductory Statistics: Key Concepts and Methods
 04:24

Termini in questo insieme (28)
Statistics is the science of learning from data, connecting data to real-world decisions by collecting, analyzing, interpreting results, and making informed decisions under uncertainty.
1. Ask and formulate a research question
2. Collect relevant data
3. Describe and explore the data
4. Analyze and interpret results
5. Draw conclusions.
Descriptive statistics summarize and describe observed data (e.g., averages, tables). Inferential statistics use sample data to draw conclusions about a population.
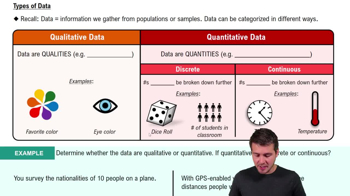
Data are recorded characteristics or observations. Types: Numerical (quantitative) - measurements or counts; Categorical (qualitative) - labels or categories.
Discrete data take countable values (e.g., number of children). Continuous data can take any value within a range (e.g., height, temperature).
Nominal: categories with no natural order (e.g., eye color). Ordinal: categories with meaningful order (e.g., pain level: mild, moderate, severe).
Some numbers serve as identifiers (e.g., student ID) and do not represent quantities, so arithmetic operations like averaging are meaningless.
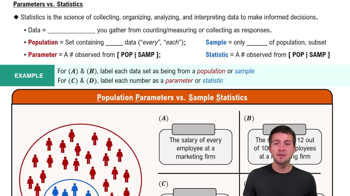
Population: entire group of interest. Sample: subset of the population actually observed or studied.
Studying entire populations is often impossible, time-consuming, or expensive. Samples allow us to make inferences about populations efficiently.
Parameter: descriptive measure of a population (usually unknown). Statistic: descriptive measure of a sample (known and calculated).
A proportion is the fraction of observations with a particular characteristic, ranging from 0 to 1.
Variability describes how much data values differ from each other; low variability means values are similar, high variability means values are spread out.
Range, Variance, Standard deviation, and Interquartile Range (IQR).
Primary data are collected firsthand (e.g., surveys, experiments). Secondary data are previously collected by others (e.g., census data).
Observational studies observe without intervention; experiments apply treatments to study effects and can establish causation.
Manipulation, Control group, Randomization, and Replication.
Random sampling selects who is in the study to represent the population. Random assignment assigns treatments to subjects to create comparable groups.
Blinding prevents expectations from influencing results. Single-blind: subjects unaware of treatment; double-blind: both subjects and researchers unaware.
Every individual in the population has an equal chance of being selected, often using random number generators.
Population divided into subgroups (strata), then random samples are taken from each stratum to ensure representation.
Population divided into clusters; some clusters are randomly selected, and all individuals in those clusters are surveyed.
Stratified sampling selects some individuals from all groups; cluster sampling selects all individuals from some groups.
Bias is a systematic error causing results to consistently misrepresent the population, often due to poor sampling or data collection.
Response bias occurs when participants give inaccurate answers due to poor recall, sensitive questions, or leading wording.
Occurs when selected individuals do not respond and their absence is related to the outcome, making results unrepresentative.
When some groups in the population are inadequately represented or excluded from the sample, leading to distorted results.
Convenience sampling (easiest to reach) and voluntary response sampling (participants self-select), both prone to bias.
Experimental units are paired based on similarity or measured twice; each pair receives different treatments to control variability.