 Indietro
Introductory Statistics: Week 1 Key Concepts
 04:24

Termini in questo insieme (20)
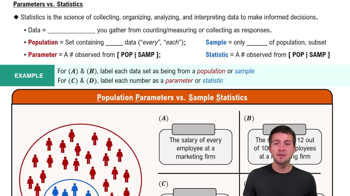
A population is the entire group a study aims to describe, while a sample is a subset of the population actually observed or measured.
A parameter describes a population (e.g., average height of all women is 63.7 inches). A statistic describes a sample (e.g., average height of 200 women sampled is 63.0 inches).
Differences arise due to sample size being too small, random sample-to-sample variation, or an incorrect parameter.
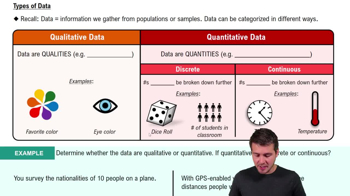
Quantitative data are numeric with meaningful arithmetic (e.g., age, height). Categorical data are labels or groups (e.g., gender, favorite color).
Discrete data are countable, separate values (e.g., die rolls). Continuous data vary across a continuum and can be measured with precision (e.g., height, blood volume).
If values can be listed in a counting system (countably infinite), data are discrete; if not (uncountable), data are continuous.
1. Prepare: define purpose, population, sample, and variables.
2. Analyze: create graphs, compute statistics, identify outliers.
3. Conclude: interpret findings and assess significance.
Exact numerical data allow detailed calculations and can be categorized later, while broad categories lose detail permanently.
An outlier is a value far from others; it may be real or an error. Investigate plausibility, decide to keep or omit it, and report handling transparently.
Systematic sampling selects every kth member, e.g., surveying every 10th student on a roster.
Convenience sampling selects easiest participants. Snowball sampling is a subtype where participants help identify others, useful for hard-to-find populations.
Stratified sampling divides population into subgroups and samples from each.
Cluster sampling divides into groups, selects some groups, and surveys all members in chosen groups.
It is practical for geographically scattered populations and provides complete info on selected groups, trading breadth for depth.
Bias from samples where participation is voluntary, as respondents may differ systematically from non-respondents.
Sampling error: random variation between samples.
Nonsampling error: human or design errors.
Nonrandom sampling error: biased sample selection.
Respondents may misreport data (e.g., weight). Researchers may ask leading questions or design biased studies.
Statistical significance means results are unlikely due to chance.
Practical significance means results are meaningful or useful in real life.
Large samples can detect tiny differences that have little real-world importance.
A sample where every member of the population has an equal chance of selection, and every possible sample of size n is equally likely.
Researchers must acknowledge potential bias and attempt to reach opposing groups to mitigate skew.