 Indietro
How Genes Work: The Central Dogma, Genetic Code, and Mutations
Guida di studio - Note intelligenti
 Appunti personalizzati basati sui tuoi materiali, ampliati con definizioni chiave, esempi e contesto.
How Genes Work
Introduction to Gene Expression
Genes are fundamental units of heredity, encoding instructions for the synthesis of molecules essential for cellular function. The process of gene expression involves converting information stored in DNA into functional molecules, primarily proteins, within the cell.
Gene Expression: The process by which information from a gene is used to synthesize a functional gene product, often a protein.
DNA: Known as the blueprint of life, it stores genetic information.
Gene Expression at the Molecular Level: Involves transcription and translation, converting DNA information into proteins.
The One-Gene, One-Enzyme Hypothesis
Historical Perspective and Modern Understanding
Early experiments led to the hypothesis that each gene contains the information to make a single enzyme. This concept evolved into the one-gene, one-polypeptide hypothesis, recognizing that genes encode polypeptides, which may function as enzymes or other proteins.
One-Gene, One-Enzyme Hypothesis: Each gene encodes a specific enzyme.
One-Gene, One-Polypeptide Hypothesis: Most genes encode polypeptides, not just enzymes.
Proteins: The majority of gene products are proteins, which perform diverse cellular functions.
The Central Dogma of Molecular Biology
Flow of Genetic Information
The central dogma describes the directional flow of genetic information within cells: DNA codes for RNA, which codes for proteins. This framework explains how genes specify the production of proteins, the molecules responsible for most cellular activities.
Central Dogma: DNA → RNA → Protein
Genes: Stretches of DNA that code for proteins.
DNA Sequence: Codes for RNA sequence.
RNA Sequence: Codes for amino acid sequence in proteins.
RNA as the Intermediary
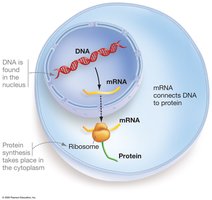
Messenger RNA (mRNA) serves as the intermediary between DNA in the nucleus and protein synthesis in the cytoplasm. RNA polymerase synthesizes RNA by using a DNA strand as a template, copying the genetic code by matching complementary nucleotides.
mRNA: Carries genetic information from DNA to the site of protein synthesis.
RNA Polymerase: Enzyme that synthesizes RNA from a DNA template.
Transcription and Translation
Transcription is the process of making a complementary RNA copy from a DNA template. Translation is the process of synthesizing proteins using the information in mRNA, interpreting the nucleotide sequence into amino acids.
Transcription: DNA → RNA (copying genetic information).
Translation: RNA → Protein (interpreting genetic information).
Linking Genotypes to Phenotypes
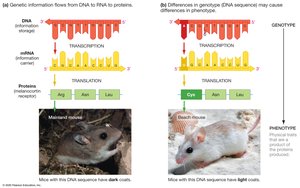
An organism’s genotype is determined by the sequence of bases in its DNA, while its phenotype is the product of the proteins it produces. Alleles of the same gene differ in DNA sequence, resulting in proteins with different amino acid sequences and potentially different phenotypes.
Genotype: Genetic makeup (DNA sequence).
Phenotype: Observable traits (product of proteins).
Alleles: Variants of a gene with different DNA sequences.
Modifications to the Central Dogma
Some genes code for RNAs that are not translated into proteins but perform important cellular functions. Additionally, certain viruses can reverse the flow of information, synthesizing DNA from an RNA template using reverse transcriptase.
Non-coding RNAs: RNAs that are not translated but have functional roles.
Reverse Transcriptase: Enzyme in some viruses that synthesizes DNA from RNA.
The Genetic Code
Structure and Function of the Genetic Code
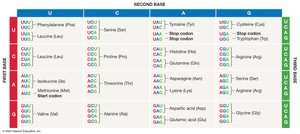
The genetic code specifies how a sequence of nucleotides in DNA or RNA codes for a sequence of amino acids in a protein. The code is composed of codons, which are groups of three bases that specify particular amino acids.
Codon: A triplet of nucleotides that specifies an amino acid.
Triplet Code: Three-base code, allowing for 64 possible codons.
Start Codon: AUG (methionine), signals the start of protein synthesis.
Stop Codons: UGA, UAA, UAG, signal the end of protein-coding sequence.
Properties of the Genetic Code
The genetic code is characterized by several important properties that ensure accurate translation of genetic information.
Redundant: Most amino acids are encoded by more than one codon.
Unambiguous: Each codon specifies only one amino acid.
Non-overlapping: Codons are read one at a time.
Nearly Universal: The code is conserved across most organisms.
Conservative: Codons for the same amino acid often share the first two bases.
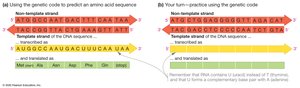
Using the Genetic Code
Biologists can predict the amino acid sequence encoded by a DNA sequence and determine the DNA or mRNA sequence that could code for a particular amino acid sequence. Due to redundancy, multiple DNA sequences can code for the same protein.
Application: Predicting protein sequences from genetic information.
Example: Translating a DNA sequence to an amino acid sequence using the genetic code.
Types and Consequences of Mutation
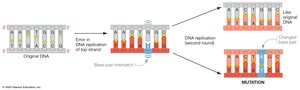
Definition and Types of Mutation
A mutation is any permanent change in an organism’s DNA, resulting in a modification of its genotype and potentially creating new alleles. Mutations can be classified as point mutations or chromosome-level mutations.
Point Mutations: Changes affecting one or a few bases.
Chromosome-Level Mutations: Larger-scale changes affecting chromosome structure or number.
Point Mutations
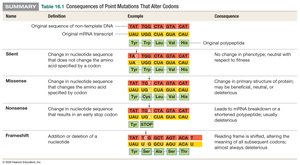
Point mutations can alter the protein-coding sequence in various ways, affecting the resulting protein and potentially the organism’s fitness.
Missense Mutation: Changes an amino acid in the protein.
Silent Mutation: Does not change the amino acid sequence due to code redundancy.
Frameshift Mutation: Shifts the reading frame, altering all subsequent codons.
Nonsense Mutation: Changes a codon to a stop codon, terminating protein synthesis prematurely.
Consequences of Point Mutations
Mutations can be beneficial, neutral, or deleterious, depending on their effect on the organism’s fitness. Most point mutations are neutral or deleterious, but some can affect phenotype by altering gene expression.
Beneficial: Increase fitness.
Neutral: No effect on fitness.
Deleterious: Decrease fitness.
Chromosome Mutations
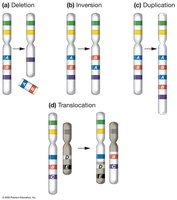
Chromosome mutations involve changes in chromosome number or structure, such as polyploidy, aneuploidy, inversion, translocation, deletion, and duplication. These mutations can have significant effects on phenotype and are often observed in cancer cells.
Inversion: Segment breaks off, flips, and rejoins.
Translocation: Segment attaches to another chromosome.
Deletion: Segment is lost.
Duplication: Segment is present in multiple copies.
Karyotypes and Chromosome-Level Mutations
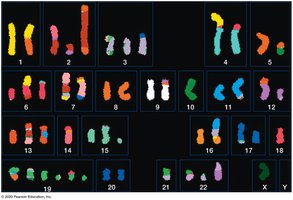
Karyotypes, which display the complete set of chromosomes in a cell, can reveal chromosome-level mutations such as aneuploidy, inversions, translocations, deletions, and duplications.
Summary Table: Types of Point Mutations
Type | Definition | Example | Consequence |
|---|---|---|---|
Silent | Change in nucleotide sequence that does not change amino acid specified by a codon | UAU → UAC (both code for Tyr) | No change in phenotype; neutral with respect to fitness |
Missense | Change in nucleotide sequence that changes the amino acid specified by a codon | UAU → UGU (Tyr → Cys) | Change in primary structure of protein; may be beneficial, neutral, or deleterious |
Nonsense | Change in nucleotide sequence that results in an early stop codon | UAU → UAA (Tyr → Stop) | Leads to mRNA breakdown or a shortened polypeptide; usually deleterious |
Frameshift | Addition or deletion of a nucleotide | TAT → TAA (reading frame shifted) | Reading frame is shifted, altering the meaning of all subsequent codons; usually deleterious |
