 Back
Introductory Statistics Review Guidance: Lessons 1–7
Study Guide - Smart Notes
 Tailored notes based on your materials, expanded with key definitions, examples, and context.
Q1. What is the difference between numeric (quantitative) and categorical data? Give examples of each.
Background
Topic: Types of Data
This question tests your understanding of the two main types of data in statistics: numeric (quantitative) and categorical (qualitative).
Key Terms:
Numeric (Quantitative) Data: Data that represent measurable quantities and have units (e.g., height, weight, test scores).
Categorical (Qualitative) Data: Data that represent categories or groups (e.g., gender, color, type of car).
Step-by-Step Guidance
Recall that numeric data are measurements that can be expressed with numbers and units, while categorical data are labels or names for groups.
Think of examples for each type: For numeric, consider things you can measure (like height in inches). For categorical, consider things you can sort into groups (like favorite color).
Be careful: Some variables use numbers but are not truly numeric (e.g., phone numbers, zip codes).
Try solving on your own before revealing the answer!
Final Answer:
Numeric data are measurable quantities (e.g., height, weight, test scores). Categorical data are groupings or categories (e.g., gender, eye color, type of car). Phone numbers are categorical, not numeric, even though they use numbers.
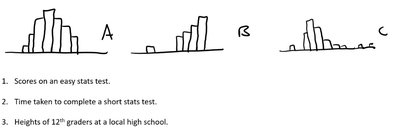
Q2. Match the variable name with the histogram by considering the likely shape of the distribution.
Background
Topic: Interpreting Histograms
This question tests your ability to interpret the shape of distributions and match them to real-world variables.
Key Terms:
Histogram: A graphical representation of the distribution of a dataset.
Distribution Shape: Can be symmetric, skewed right, or skewed left.
Step-by-Step Guidance
Examine each histogram (A, B, C) and note the shape: Is it symmetric, skewed right, or skewed left?
Consider the variable descriptions: Scores on an easy stats test, time taken to complete a short stats test, heights of 12th graders.
Recall that test scores on an easy test often cluster at the high end (left-skewed), time taken is often right-skewed, and heights are usually symmetric.
Match each variable to the histogram based on these typical distribution shapes.
Try solving on your own before revealing the answer!
Final Answer:
A: Heights of 12th graders (symmetric) B: Scores on an easy stats test (left-skewed) C: Time taken to complete a short stats test (right-skewed)
We matched the variables to the histograms based on the expected distribution shapes for each scenario.
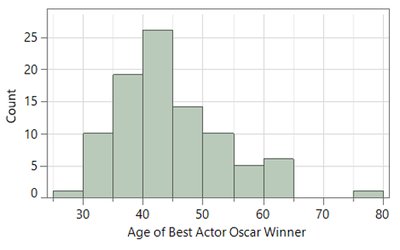
Q3. This histogram shows the distribution of the ages of 92 Best Actor Oscar winners. Answer the following:
How many Best Actor winners were between 50 and 60?
How old are the oldest winners?
What has been the most frequent age range of winners?
Background
Topic: Reading Histograms
This question tests your ability to extract information from a histogram, such as counts in intervals, maximum values, and mode.
Key Terms:
Histogram: Shows frequency of data in intervals.
Mode: The most frequent value or interval.
Step-by-Step Guidance
Look at the histogram and identify the bar(s) corresponding to ages 50–60. Count the height of these bars.
Find the rightmost bar to determine the oldest winner's age.
Identify the tallest bar to find the most frequent age range.
Record the counts and age ranges for each part, but stop before stating the exact numbers.
Try solving on your own before revealing the answer!
Final Answer:
1. There are 8 Best Actor winners between 50 and 60. 2. The oldest winners are about 76–78 years old. 3. The most frequent age range is 40–45 years.
These answers are based on the heights and positions of the bars in the histogram.
Q4. If the data is skewed right, which is bigger: the mean or the median? If the data is skewed left, which is bigger: the mean or the median? What if it is symmetric?
Background
Topic: Measures of Center and Distribution Shape
This question tests your understanding of how the mean and median relate to the shape of a distribution.
Key Terms:
Mean: The arithmetic average.
Median: The middle value when data are ordered.
Skewness: Right-skewed (long tail to the right), left-skewed (long tail to the left), symmetric (balanced).
Step-by-Step Guidance
Recall that in a right-skewed distribution, the mean is pulled toward the higher values (right tail).
In a left-skewed distribution, the mean is pulled toward the lower values (left tail).
For symmetric distributions, the mean and median are approximately equal.
Set up your answer by comparing mean and median for each case, but stop before stating the exact relationships.
Try solving on your own before revealing the answer!
Final Answer:
Right-skewed: Mean > Median Left-skewed: Mean < Median Symmetric: Mean ≈ Median
The mean is affected by extreme values in the tail, while the median is more resistant to skewness.
Q5. Suppose the heights of a sample of 200 men is recorded. The data is bell-shaped with an average of 68 inches and a standard deviation of 2.5 inches. Use the Empirical Rule to provide a rough sketch of the distribution.
Background
Topic: Empirical Rule (68-95-99.7 Rule)
This question tests your ability to apply the Empirical Rule to a normal distribution.
Key Formula:
Step-by-Step Guidance
Identify the mean ( inches) and standard deviation ( inches).
Calculate the intervals: , , .
Determine the percentage of data expected in each interval using the Empirical Rule.
Sketch or describe the bell-shaped curve, labeling the mean and the intervals for 1, 2, and 3 standard deviations.
Try solving on your own before revealing the answer!
Final Answer:
About 68% of heights are between 65.5 and 70.5 inches, 95% between 63 and 73 inches, and 99.7% between 60.5 and 75.5 inches. The distribution is bell-shaped and centered at 68 inches.
Q6. Suppose the heights of a sample of 200 men are recorded. The data is bell-shaped with an average of 68 inches and a standard deviation of 2.5 inches. Find and interpret the z-score for a 72 inch tall man. Would you consider a 74 inch tall man to be unusual relative to the other men in this data set? Explain using the z-score.
Background
Topic: Z-scores and Normal Distributions
This question tests your ability to calculate and interpret z-scores, and to determine if a value is unusual.
Key Formula:
= observed value, = mean, = standard deviation
Step-by-Step Guidance
Identify the mean (), standard deviation (), and observed values ( and ).
Plug the values into the z-score formula for each height.
Interpret the z-score: Values with are often considered unusual.
Set up the calculations for each z-score, but stop before stating the final values.
Try solving on your own before revealing the answer!
Final Answer:
For 72 inches: For 74 inches: A z-score of 2.4 is considered unusual, since it is greater than 2.
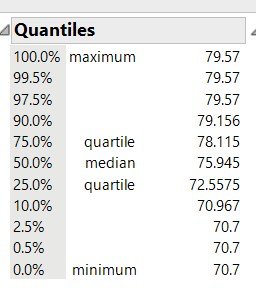
Q7. Find the 5 number summary and the Interquartile Range (IQR) using the JMP output.
Background
Topic: Five Number Summary and IQR
This question tests your ability to extract summary statistics from statistical software output.
Key Terms:
Five Number Summary: Minimum, Q1 (first quartile), Median, Q3 (third quartile), Maximum
Interquartile Range (IQR):
Step-by-Step Guidance
Locate the minimum, Q1, median, Q3, and maximum values in the JMP output.
Record each value for the five number summary.
Calculate the IQR by subtracting Q1 from Q3.
Set up the calculation for IQR, but stop before stating the final value.
Try solving on your own before revealing the answer!
Final Answer:
Five number summary: 70.7, 72.5575, 75.945, 78.115, 79.57 IQR = 78.115 - 72.5575 = 5.5575
The five number summary and IQR are extracted directly from the JMP quantiles table.
Q8. Repeat the preceding exercise by hand. You’ll notice that you get different answers than JMP which uses a somewhat more complicated method than just averaging the two numbers when there is an even number of observations.
Background
Topic: Calculating Five Number Summary and IQR by Hand
This question tests your ability to manually compute quartiles and the five number summary from a dataset.
Key Terms:
Quartiles: Divide the data into four equal parts.
Median: Middle value.
IQR: Difference between Q3 and Q1.
Step-by-Step Guidance
Order the data from smallest to largest.
Find the minimum and maximum values.
Locate the median (middle value).
Find Q1 (median of the lower half) and Q3 (median of the upper half).
Calculate the IQR as Q3 - Q1, but stop before stating the final values.
Try solving on your own before revealing the answer!
Final Answer:
By hand, the five number summary may differ slightly from JMP output due to different methods for calculating quartiles. Typically, you average the two middle values when there is an even number of observations.
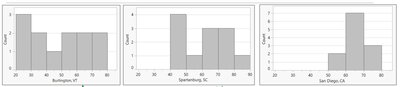
Q9. Order the following data sets by the size of the standard deviation.
Background
Topic: Standard Deviation and Spread
This question tests your ability to visually compare the spread of different distributions using histograms.
Key Terms:
Standard Deviation: A measure of spread or variability in a dataset.
Histogram: Shows the distribution and spread of data.
Step-by-Step Guidance
Examine each histogram and note how spread out the data are.
Compare the width of the distributions: Wider distributions have larger standard deviations.
Order the data sets from smallest to largest spread based on the visual width.
Set up your answer, but stop before stating the exact order.
Try solving on your own before revealing the answer!
Final Answer:
San Diego, CA has the smallest standard deviation; Burlington, VT is intermediate; Spartanburg, SC has the largest standard deviation.
The wider the histogram, the larger the standard deviation.
Q10. Below are side-by-side boxplots for Life Expectancy in six different world regions. Compare the life expectancies for South America and for Africa.
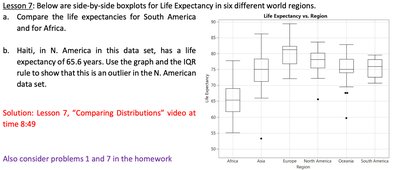
Background
Topic: Comparing Distributions with Boxplots
This question tests your ability to interpret and compare boxplots for different groups.
Key Terms:
Boxplot: Visual summary of the five number summary.
Median: Line inside the box; shows the central value.
IQR: Length of the box; shows spread.
Step-by-Step Guidance
Locate the boxplots for South America and Africa.
Compare the medians (central lines) for each region.
Compare the spread (IQR) and range for each region.
Set up your comparison, but stop before stating the exact differences.
Try solving on your own before revealing the answer!
Final Answer:
South America has a higher median life expectancy and a smaller spread compared to Africa. Africa's boxplot shows lower median and greater variability.
Q11. Haiti, in North America in this data set, has a life expectancy of 65.6 years. Use the graph and the IQR rule to show that this is an outlier in the N. American data set.
Background
Topic: Outlier Detection Using IQR Rule
This question tests your ability to use the IQR rule to identify outliers in a dataset.
Key Formula:
Any value outside these fences is considered an outlier.
Step-by-Step Guidance
Find Q1 and Q3 for North America from the boxplot or summary statistics.
Calculate the IQR ().
Compute the lower fence ().
Compare Haiti's life expectancy (65.6 years) to the lower fence, but stop before stating the final comparison.
Try solving on your own before revealing the answer!
Final Answer:
Haiti's life expectancy is below the lower fence, so it is an outlier in the North American data set according to the IQR rule.
